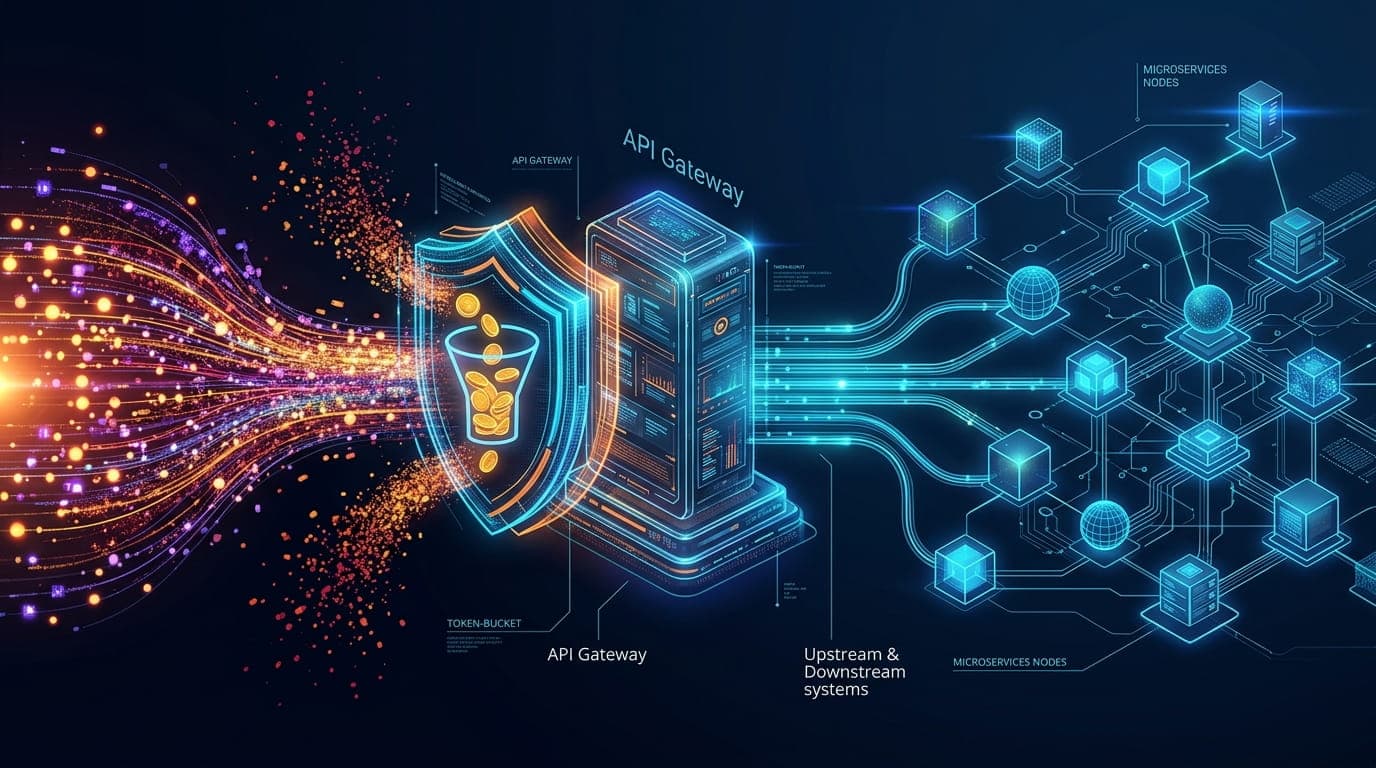
Distributed systems are bound by the realities of finite resources: CPU cycles, memory allocations, thread pools, and database connection limits. When traffic spikes exceed these physical boundaries, systems without adequate traffic management do not merely slow down; they experience catastrophic degradation. This architectural deep dive examines how to safeguard distributed systems using dynamic load shedding at the API edge and reactive backpressure across internal service boundaries.
The Anatomy of a Cascading Failure: How Local Overload Destroys Distributed Systems
A cascading failure is a phenomenon where a localized failure or resource exhaustion in one component of a distributed system propagates across the network, ultimately taking down entire clusters. Understanding this lifecycle is critical for designing resilient architectures.
Cascading failures typically follow a predictable trajectory: a downstream service (e.g., a payment processing microservice) experiences elevated latency due to a transient database lock contention. As response times increase, upstream calling services hold onto their worker threads and connection pools longer waiting for responses. Consequently, the upstream services exhaust their own thread pools. Clients experiencing timeouts begin retrying their requests, exponentially amplifying the load. This feedback loop creates a system-wide outage driven entirely by resource exhaustion rather than underlying infrastructure damage.
Failure Phase | System Behavior | Mitigation Strategy |
|---|---|---|
1. Saturation | Thread pools and connection limits reach 100% utilization. | Bulkheads and Concurrency Limits |
2. Propagation | Upstream callers block, exhausting their own resources. | Reactive Backpressure & Timeouts |
3. Amplification | Aggressive client retries flood the already degraded system. | Jittered Exponential Backoff & Load Shedding |
Implementing Admission Control and Load Shedding at the API Gateway
Admission control and load shedding at the API gateway protect downstream microservices by proactively dropping excess requests before they consume internal cluster resources. Rather than letting every request enter the internal mesh, the gateway acts as an intelligent traffic filter.
Modern edge architectures implement adaptive load shedding using algorithms like Little's Law, token buckets, and gradient-based load shedding. Instead of relying on static rate limits, dynamic load shedding monitors system health metrics—such as CPU utilization, memory pressure, and queue depth—calculating an instantaneous drop probability. When the drop probability exceeds zero, incoming requests are rejected immediately with an HTTP 429 (Too Many Requests) or HTTP 503 (Service Unavailable) status code, preserving system throughput for active workloads.
<?php

class TokenBucketLoadshedder {
    private float $capacity;
    private float $tokens;
    private float $refillRate;
    private float $lastRefillTimestamp;

    public function __construct(float $capacity, float $refillRate) {
        $this->capacity = $capacity;
        $this->tokens = $capacity;
        $this->refillRate = $refillRate; // tokens per second
        $this->lastRefillTimestamp = microtime(true);
    }

    private function refill(): void {
        $now = microtime(true);
        $elapsed = $now - $this->lastRefillTimestamp;
        $this->lastRefillTimestamp = $now;

        $this->tokens = min(
            $this->capacity,
            $this->tokens + ($elapsed * $this->refillRate)
        );
    }

    public function allowRequest(float $cost = 1.0): bool {
        $this->refill();

        if ($this->tokens >= $cost) {
            $this->tokens -= $cost;
            return true;
        }

        return false;
    }
}

// Usage at API Gateway entrypoint
$shedder = new TokenBucketLoadshedder(100.0, 50.0);
if (!$shedder->allowRequest()) {
    http_response_code(429);
    header('Retry-After: 5');
    echo json_encode(['error' => 'System overloaded. Please try again later.']);
    exit;
}
Managing Internal Service Boundaries with Reactive Backpressure and Bounded Queues
Reactive backpressure allows downstream services to signal their capacity constraints upstream, preventing fast producers from overwhelming slow consumers. Unbounded queues are a notorious anti-pattern in distributed systems; they mask downstream congestion while silently consuming heap memory until an Out-Of-Memory (OOM) crash occurs.
To implement safe internal communication, replace unbounded queues with bounded, drop-tail or ring-buffer queues. In gRPC and asynchronous messaging pipelines (such as Kafka or RabbitMQ), backpressure is enforced via flow-control windows and reactive streams specifications. When a consumer's processing buffer reaches its high-water mark, it signals upstream publishers to pause or reduce the rate of emission. If publishers ignore the signal, circuit breakers trip, isolating the fault.
Protecting Thread Pools and Database Connections Under Extreme Concurrency
Thread pool starvation occurs when all available worker threads are blocked waiting on I/O operations, database queries, or external HTTP calls. This leaves no threads available to process incoming health checks or fast in-memory computations.
Engineers must enforce strict bulkhead patterns to isolate critical execution paths. By separating thread pools for different downstream dependencies (e.g., User Service vs. Recommendation Service), a failure in a non-critical subsystem cannot exhaust the worker threads required for core transactions. Furthermore, database connection pools must be configured with explicit acquisition timeouts and maximum limits aligned with database server capacities.
Bulkhead Isolation: Isolate thread pools per downstream dependency to contain blast radiuses.
Bounded Execution Queues: Reject tasks immediately when queue capacity is reached rather than queuing indefinitely.
Adaptive Timeouts: Use dynamic timeouts that shorten as system load increases to fail fast.
Defining Failure Strategies: Graceful Degradation, Priority-Based Dropping, and Fail-Fast Patterns
When load shedding and backpressure mechanisms activate, the system must handle dropped or rejected work intelligently. Designing robust failure strategies ensures that user experience remains functional even when peripheral features fail.
Priority-based dropping ensures that mission-critical transactions (e.g., cart checkout, authentication) are protected while non-critical operations (e.g., recommendations, analytics tracking, view counters) are shed first. Additionally, implement graceful degradation by returning cached fallback data, static default responses, or partially rendered UI components rather than outright errors whenever possible. Combined with fail-fast client behavior, these patterns transform brittle systems into resilient, fault-tolerant distributed architectures.
Limits of the token-bucket example
The PHP object above is an in-memory, fixed-rate token bucket, not an adaptive cluster-wide load shedder. Creating a fresh object for each PHP request resets it to full capacity. It only limits a stream of requests when the same object survives across admissions in a long-lived process. Multiple workers would each have their own independent bucket.
For a shared limit, use a gateway limiter or an atomic shared-store implementation with a defined key scope. For capacity-based shedding, separately measure the resource you intend to protect, such as active requests or a bounded queue. Rate limits constrain arrivals; concurrency limits constrain work already in flight.
A useful isolated test fills the configured bucket, verifies that the next admission is rejected, advances a controllable clock and verifies refill without exceeding capacity. Also test multiple workers and clients retrying after rejection. Validate positive capacity, refill rate and request cost; the abbreviated class does not include that input validation.
Choose a rejection status that describes the condition: a client rate limit and temporary service overload are different situations. Keep retries bounded, honor a valid retry delay and avoid retrying non-idempotent work without an explicit recovery design. The example does not establish a measured capacity for a production system.